Preparing your learning space...
100% through Integrations & APIs tutorials
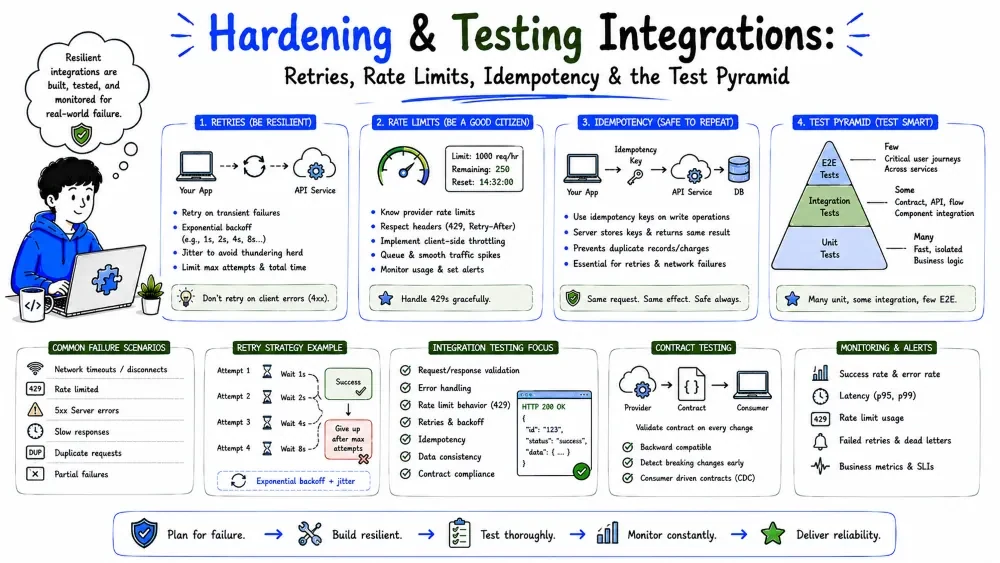
Every integration eventually hits an error, most eventually hit a rate limit, and every integration needs proof it still works. This tutorial covers the two halves of making an integration trustworthy: hardening it against failure (status codes, retries, backoff, idempotency) and testing it (the pyramid, sandboxes, mocking, failure paths, and webhook tests).
Every integration fails in one of two roughly distinct ways:
429, a 5xx, a brief blip. It might pass if you just wait and try again.400/404 (bad request), bad auth (401/403), a schema change in the payload. No retry will fix it — you must fix your code.Your first job in an error handler is: tell these two apart. Retrying a permanent failure is how integrations spin forever on the same broken request.
Never assume success because no exception was raised. A 400 with an error body is still a valid HTTP response — your code must check the code and the body it was given:
import requests, os

resp = requests.post(
    "https://api.e.g/v1/accounts",
    json={"external_id": "c_42", "name": "Acme"},
    headers={"Authorization": f"Bearer {os.getenv('TOKEN')}"},
    timeout=30,
)
if resp.status_code >= 400:
    # permanent vs transient decision happens here (next section)
    raise RuntimeError(f"API error {resp.status_code}: {resp.text[:200]}")
Simplify by grouping status codes into three actionable buckets:
| Class | Codes | Meaning |
|---|---|---|
| Success | 2xx | It worked. Log and move on. |
| Retryable / transient | 408, 429, 5xx, network errors | Maybe wait & retry (backoff). |
| Fatal / permanent | 400, 401, 403, 404, 409 | A bug in your code or config — fix it, retrying won't help. |
Best Practice: map codes to one of these three buckets up front. Then your handler becomes a clean three-way decision instead of an unreadable wall of elifs.
A missing timeout is the #1 way integrations hang silently. A request without a timeout can sit there forever while your job sits there too:
import requests

resp = requests.get(url,               # BAD
    headers=headers)
# if the API never returns, this line never runs — your whole job hangs
Always pass a timeout, and treat a timeout like the retryable error it is:
resp = requests.get(url, headers=headers, timeout=30)
Explanation: timeout=30 bounds how long we'll wait for a response. Combined with retrying on timeout, a hung or slow server becomes a handled case instead of a permanent hang.
When you decide it's retryable, never hammer it instantly. Back off, exponentially. Exponential + jitter is the standard — it spreads retries so they don't all sync up, and it behaves reasonably under bursts:
import time, requests, random

def get(url, headers, tries=5, base=2, max_delay=60):
    for i in range(tries):
        try:
            r = requests.get(url, headers=headers, timeout=30)
            if r.status_code in (408, 429) or r.status_code >= 500:
                delay = min(base ** i, max_delay)
                time.sleep(delay + random.uniform(0, delay))
                continue
            r.raise_for_status()
            return r.json()
        except requests.RequestException:
            if i == tries - 1:
                raise
            delay = min(base ** i, max_delay)
            time.sleep(delay + random.uniform(0, delay))
    raise RuntimeError(f"gave up on {url}")
Explanation: each failed attempt waits 2**i seconds plus a little random jitter, capped at max_delay. Randomness avoids synchronized "thundering-herd" retries when 100 jobs all fail at once. Exponential growth makes early retries quick but later ones far apart.
429 & Retry-After429 Too Many Requests is the API telling you to slow down (Tutorial 3's pattern). Honor the server hint first:
if r.status_code == 429:
    wait = int(r.headers.get("Retry-After", 2 ** i))
    time.sleep(wait)
    continue
Best Practice: prefer the server's Retry-After header when present; fall back to exponential backoff when absent. Retrying 429 without slowing down is how you get banned.
5xx Retry, the 4xx Do-Not5xx, 408, network errors → safe to retry (transient).4xx (except 408) → almost always do NOT retry — a bug in your request, not a server blip. Log it, raise an alert, and let a human look.Note: 409 Conflict (duplicate) is sometimes actually idempotent-safe — retry against the same key is the fix. That's when idempotency keys + PUT/DELETE (safe) retry wins.
Retrying is only safe if the call is idempotent — running it twice gives the same result (Data Engineering Tutorial 5, HTTP Tutorial 1):
GET, PUT, DELETE — safe to retry: same operation, same result.POST — not safe: a retry can double-create. Two ways to make it safe:
# safe retry on a POST that creates: use an idempotency key
requests.post(url, json={"idempotency_key": "retry-42-001"}, timeout=30)
Explanation: for charge/order/email POSTs that you might retry, include an idempotency key. The server remembers the key and, if the same key arrives again, returns the prior result instead of acting twice. That's how you make the dangerous verb safe to retry.
The whole hardening, composed into one reusable piece:
import time, random, requests

def call(url, headers, json=None, method="GET", tries=5):
    for i in range(tries):
        try:
            r = requests.request(method, url, headers=headers, json=json, timeout=30)
            if r.status_code == 429:
                time.sleep(int(r.headers.get("Retry-After", 2 ** i)))
                continue
            if r.status_code < 500 or r.status_code == 408:
                r.raise_for_status()   # anything 4xx that isn't 429 fails fast
            if i == tries - 1:
                r.raise_for_status()
            time.sleep(min(2 ** i, 30) + random.uniform(0, 1))
        except requests.RequestException:
            if i == tries - 1:
                raise
            time.sleep(min(2 ** i, 30) + random.uniform(0, 1))
    return r.json()
This one function covers timeout, retry-with-jitter, 429+Retry-After, the 5xx-retry policy, and fail-fast on 4xx — the whole hardening playbook in ~25 lines.
Unit tests check a function in isolation. Integration tests check the seam between your code and someone else's system — the place where auth, formats, schemas, and network behavior actually collide. The things that break most often in integrations (a field rename, a 429, a schema drift) only show up at this seam, so they need their own tests.
An integration test verifies four things at once:
Best Practice: treat an integration test as a contract test — it's your tripwire for when the other system changes under you. When it fails, either they changed their API or your mapping is stale.
      /\   A few  end-to-end tests (real systems, slow, precious)
     /  \
    /    \   Some    integration tests (sandbox + real HTTP)
   /      \
  /________\  Many   unit tests (mocked API, fast, cheap)
Default to the fast bottom of the pyramid; reserve the expensive top for the few flows that prove the whole thing holds together.
Integration tests should target each provider's sandbox / test mode (Tutorials 3, 4) with test keys. Why:
Best Practice: keep sandbox and production credentials strictly separate, switch with an env var, and never let CI tests touch production keys. Your tests should be safe to run on any machine, any time.
Not everything can or should hit a live API in every test. Mocking replaces the API with a fake that returns canned responses, so your tests are fast and deterministic:
# mock the requests.get so the test never makes a real call
import requests
from unittest import mock

fake = mock.Mock()
fake.status_code = 200
fake.json.return_value = {"contacts": [{"id": 1, "email": "a@b.com"}]}

with mock.patch("requests.get", return_value=fake):
    data = pull_contacts()          # your function under test
    assert data[0]["email"] == "a@b.com"
Explanation: we replace requests.get with a fake returning a canned 200 response. Now the test runs instantly and predictably — it tests your parsing and logic without depending on the network.
Note: mock for the fast, logic-heavy tests (parsing, mapping, error branches). Keep a small set of real sandbox tests to prove the actual HTTP/auth works. Mock-only is how an integration passes tests while being broken against the real API.
Every integration needs at least one happy-path test: send a valid request, get a success, and confirm the result is what you expect.
def test_push_contact_success():
    # against a sandbox, or with the HTTP layer mocked
    result = push_contact({"id": 42, "first": "Amy", "last": "Xu"})
    assert result == 42                 # the id returned by the target
Explanation: we call push_contact with a normal record and assert the returned id. This catches the common breakage where a field rename or changed response shape silently breaks a working flow.
The failure handling you built in Part 1 is only trustworthy if you test it. Cover the three buckets:
def test_retries_on_429():
    # first call returns 429, second returns 200
    responses = [mock_429, mock_200]
    # with get_with_retry patched to return these in sequence...
    result = get_with_retry(url, headers)
    assert responses.count(calls) == 2   # it retried exactly once

def test_fails_fast_on_400():
    with pytest.raises(RuntimeError):
        get_with_retry(url, headers)     # a 400 must NOT retry
Explanation: the 429 test proves your code backs off and retries; the 400 test proves it does not retry a permanent error. These two tests are the difference between a handled failure and an integration that spins forever.
The mapping table from Tutorial 5 is the easiest thing to get wrong and the cheapest to test. Feed it edge cases and assert the output:
def test_full_name_concat():
    assert map_contact({"first": "Amy", "last": "Xu"})["name"] == "Amy Xu"

def test_null_fields_do_not_crash():
    assert map_contact({"first": None, "last": "Xu"})["name"] == "Xu"
Explanation: unit-test the field mapping with normal and edge inputs (missing fields, nulls, empty strings). Contract tests like these catch most schema-drift surprises before they reach the real system.
Webhook handlers (Tutorial 3) need special tests because the payload arrives from the outside:
400).type takes the right branch.def test_rejects_bad_signature():
payload = json.dumps({"type": "order.created"}).encode()
assert verify("v1=wrongsig", payload) is False
def test_duplicate_event_not_reprocessed():
handle_event(event_a)
handle_event(event_a) # same id again
assert create_count == 1 # deduplicated by event id
Explanation: one test proves forged events are rejected; another proves a redelivered event (which providers do on failure) doesn't duplicate work. These are the two ways webhooks silently go wrong, now pinned down.
Automate the tests you can run safely and fast:
Best Practice: make the sandbox tests a scheduled job, not just a pre-release one. An API that quietly changes field names only surfaces if your tests keep running against it over time.
Save your progress and earn XP for completing tutorials.
4 questions · Pass with 70%+
1Which failures should your code retry?
2A request without a timeout can lead to...
3In the testing pyramid, the bulk of tests should be...
4How do you verify a webhook really came from the provider... and redelivery won't duplicate?
Technology
Forward Deployed Engineer
Lesson group
Integrations & APIs
Progress
100% complete

