Preparing your learning space...
86% through Querying Data tutorials
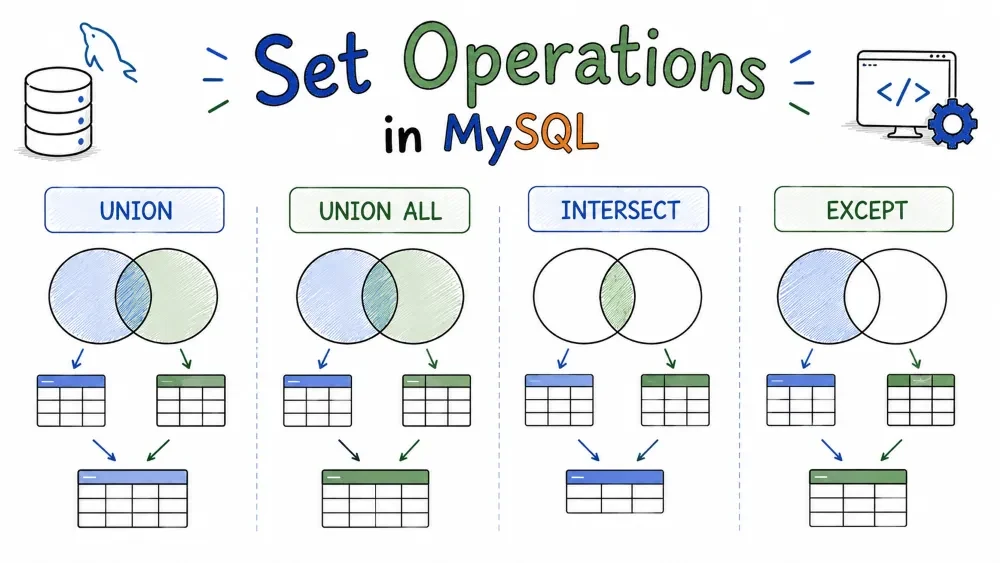
Set operations combine rows from two or more query results. They treat each SELECT result as a set and apply union, intersection, or difference logic — no joins required.
All examples below use these sample tables:
CREATE TABLE customers (
  name VARCHAR(50),
  city VARCHAR(50)
);

CREATE TABLE suppliers (
  name VARCHAR(50),
  city VARCHAR(50)
);

INSERT INTO customers VALUES
  ('Alice', 'Berlin'),
  ('Bob',   'Munich'),
  ('Eve',   'Berlin');

INSERT INTO suppliers VALUES
  ('S1', 'Berlin'),
  ('S2', 'Cologne'),
  ('S3', 'Munich');
customers              suppliers
+-------+--------+    +------+---------+
| name  | city   |    | name | city    |
+-------+--------+    +------+---------+
| Alice | Berlin |    | S1   | Berlin  |
| Bob   | Munich |    | S2   | Cologne |
| Eve   | Berlin |    | S3   | Munich  |
+-------+--------+    +------+---------+
Both stack results from multiple SELECT queries vertically (row-wise). The difference: UNION removes duplicates, UNION ALL keeps everything.
SELECT must have the same number of columns.SELECT.SELECT city FROM customers
UNION
SELECT city FROM suppliers
ORDER BY city;
Result:
+---------+
| city    |
+---------+
| Berlin  |
| Cologne |
| Munich  |
+---------+
Each city appears once, even if it exists in both tables.
SELECT city FROM customers
UNION ALL
SELECT city FROM suppliers
ORDER BY city;
Result:
+---------+
| city    |
+---------+
| Berlin  |  <- customers
| Berlin  |  <- customers
| Berlin  |  <- suppliers
| Cologne |
| Munich  |  <- customers
| Munich  |  <- suppliers
+---------+
Every row from both queries is returned. Berlin and Munich appear twice — once from each table.
UNION ALL is especially important with large datasets — UNION can slow down significantly because dedup requires comparing every row.
Put ORDER BY at the very end — it sorts the final merged set, not individual queries.
SELECT name, 'Customer' AS type FROM customers
UNION
SELECT name, 'Supplier' FROM suppliers
ORDER BY name;
You can't sort each SELECT individually (unless you wrap them in subqueries).
INTERSECT returns only rows that exist in both result sets.
SELECT city FROM customers
INTERSECT
SELECT city FROM suppliers
ORDER BY city;
Result:
+---------+
| city    |
+---------+
| Berlin  |
| Munich  |
+---------+
Berlin and Munich are the cities that appear in both tables. Cologne is out — it only exists in suppliers.
MySQL's
INTERSECTonly returns distinct rows (likeINTERSECT DISTINCT). It does not supportINTERSECT ALL.
If your MySQL version is older than 8.0.31, use one of these:
-- Using EXISTS (recommended)
SELECT DISTINCT city FROM customers c
WHERE EXISTS (SELECT 1 FROM suppliers s WHERE s.city = c.city);

-- Using IN
SELECT DISTINCT city FROM customers
WHERE city IN (SELECT city FROM suppliers);

-- Using INNER JOIN
SELECT DISTINCT c.city
FROM customers c
INNER JOIN suppliers s ON c.city = s.city;
EXISTS is usually the fastest when the right table is large — it stops scanning as soon as it finds a match.
EXCEPT (called MINUS in Oracle) returns rows from the first query that are not in the second.
SELECT city FROM customers
EXCEPT
SELECT city FROM suppliers
ORDER BY city;
Result: empty set. Every city in customers (Berlin, Munich) also exists in suppliers, so nothing is left after subtracting the overlap.
To find cities exclusive to one table, swap the query order:
SELECT city FROM suppliers
EXCEPT
SELECT city FROM customers
ORDER BY city;
Result:
+---------+
| city    |
+---------+
| Cologne |
+---------+
Cologne is the only city that appears in suppliers but not in customers.
With SELECT *, EXCEPT compares entire rows — every column must match to be excluded:
SELECT * FROM customers
EXCEPT
SELECT * FROM suppliers
ORDER BY city;
Result: all three customer rows. No row in customers is identical to any row in suppliers (different names, and not every city matches), so nothing gets subtracted.
Like
INTERSECT, MySQL'sEXCEPTonly returns distinct rows. It does not supportEXCEPT ALL.
-- Using NOT EXISTS (recommended — NULL-safe)
SELECT DISTINCT city FROM customers c
WHERE NOT EXISTS (SELECT 1 FROM suppliers s WHERE s.city = c.city);
Result:
Empty set (no cities that exist only in customers)
With our data every customer city also has a supplier, so the result is empty. If you want cities that are in suppliers but not in customers, swap the order:
SELECT DISTINCT city FROM suppliers s
WHERE NOT EXISTS (SELECT 1 FROM customers c WHERE c.city = s.city);
Result:
+---------+
| city    |
+---------+
| Cologne |
+---------+
-- Using NOT IN (watch out for NULLs!)
SELECT DISTINCT city FROM customers
WHERE city NOT IN (SELECT city FROM suppliers WHERE city IS NOT NULL);

-- Using LEFT JOIN / IS NULL
SELECT DISTINCT c.city
FROM customers c
LEFT JOIN suppliers s ON c.city = s.city
WHERE s.city IS NULL;
Recommendation: use
NOT EXISTS— it's readable, NULL-safe, and usually performs well.
Both combine data from multiple tables, but they work differently.
| Aspect | UNION | JOIN |
|---|---|---|
| Direction | Vertical (more rows) | Horizontal (more columns) |
| Column count | Same in all SELECTs | Matched by key |
| Duplicates | UNION removes, UNION ALL keeps | Depends on join type |
| Use case | Stacking similar result sets | Enriching rows with related data |
Example difference:
-- UNION: 2 rows (one per table)
SELECT 'Alice', 'Customer' UNION ALL SELECT 'Bob', 'Supplier';

-- JOIN: 1 row with 4 columns (if matched)
SELECT c.name, c.city, s.name, s.product
FROM customers c
JOIN suppliers s ON c.city = s.city;
Decide based on whether you need more rows (UNION) or more columns (JOIN).
Save your progress and earn XP for completing tutorials.
4 questions · Pass with 70%+
1Which MySQL set operator combines two result sets but removes duplicate rows by default?
2What is a mandatory rule when using any set operator (UNION, INTERSECT, EXCEPT)?
3Why is UNION ALL generally faster than UNION?
4Which operator returns only the rows that appear in BOTH result sets?
Technology
MySQL
Lesson group
Querying Data
Progress
86% complete

